Shruti
Hindi, English and Hinglish speech to text that runs on your device, with no server.
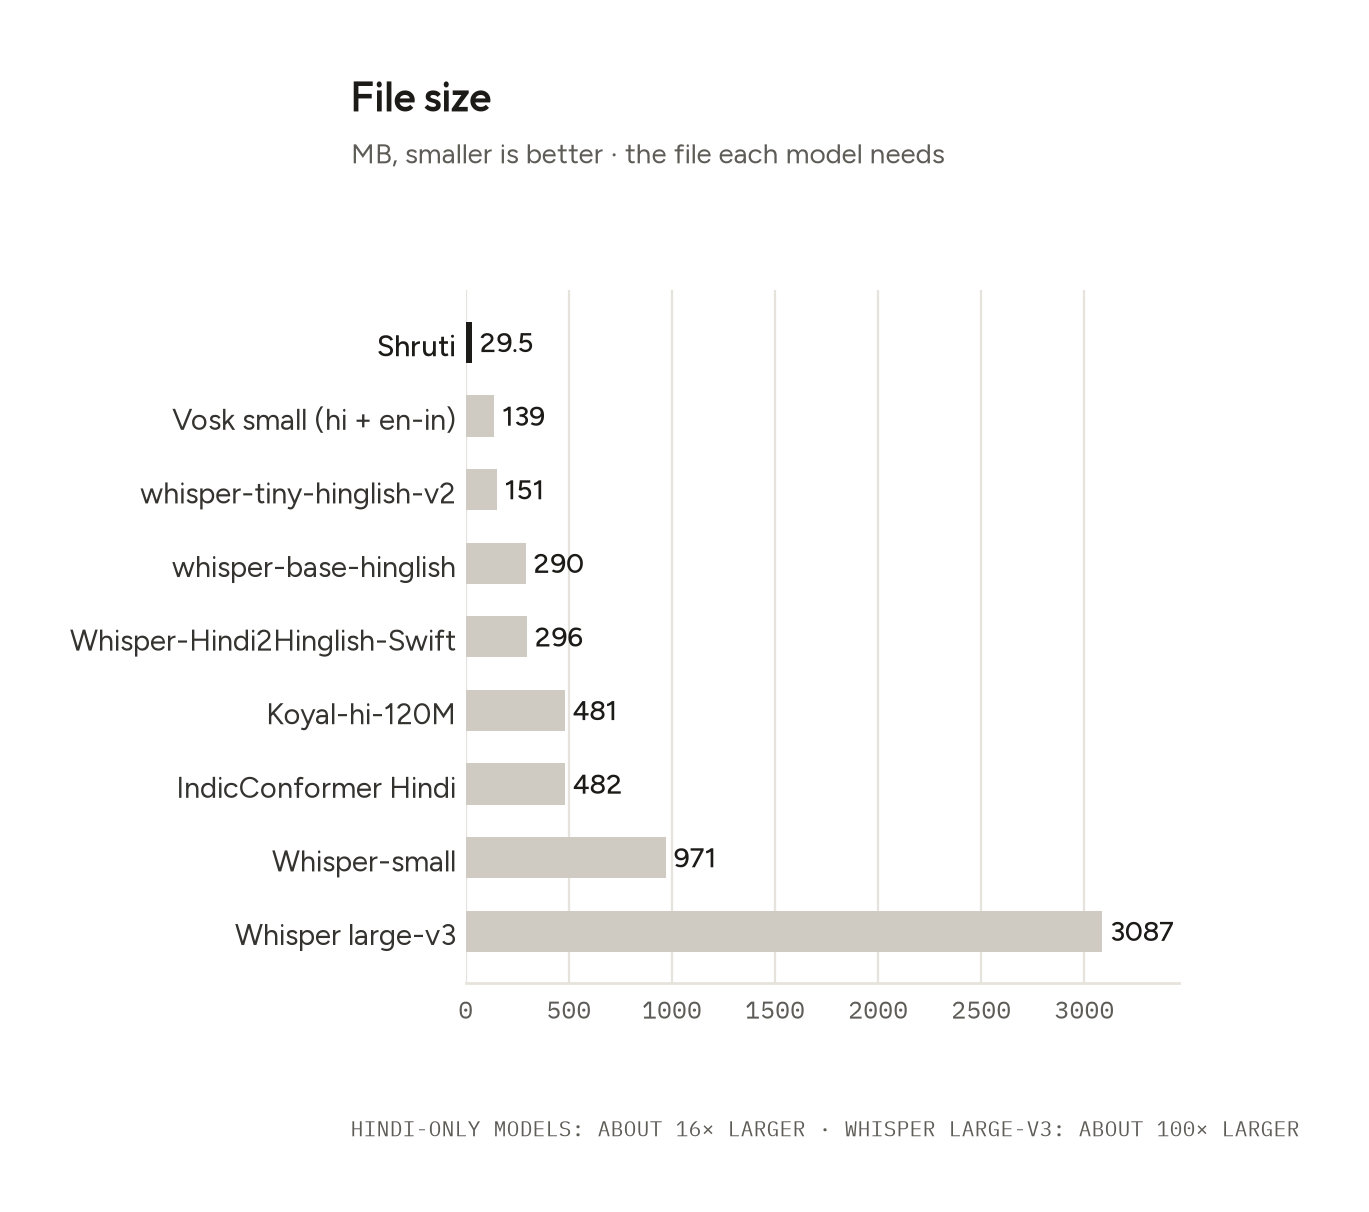
Speech to text for Hindi, English and Hinglish in one 29.5 MB file. It writes Hindi in Devanagari and English words in English, the way people type Hinglish, and runs offline: on a phone, on a laptop or in a browser tab.
Try it now · in your browser · free, no login
Speak Hindi, English or both. Shruti writes it down on your device.
Shruti · checking this device
Audio never leaves your device. Shruti and its open-source engine run inside this page.
(or drop one on the transcript)
Load Shruti, then press Record and speak Hindi, English or both.
The language is detected for you. English words stay in English (Latin script) and are underlined here; Hindi is written in Devanagari. While you speak, words appear once they have settled, a second or two behind you; when you stop, Shruti reads the whole recording once more for the final text.
The result
The smallest open model we know of that does Hindi, English and Hinglish in one file.
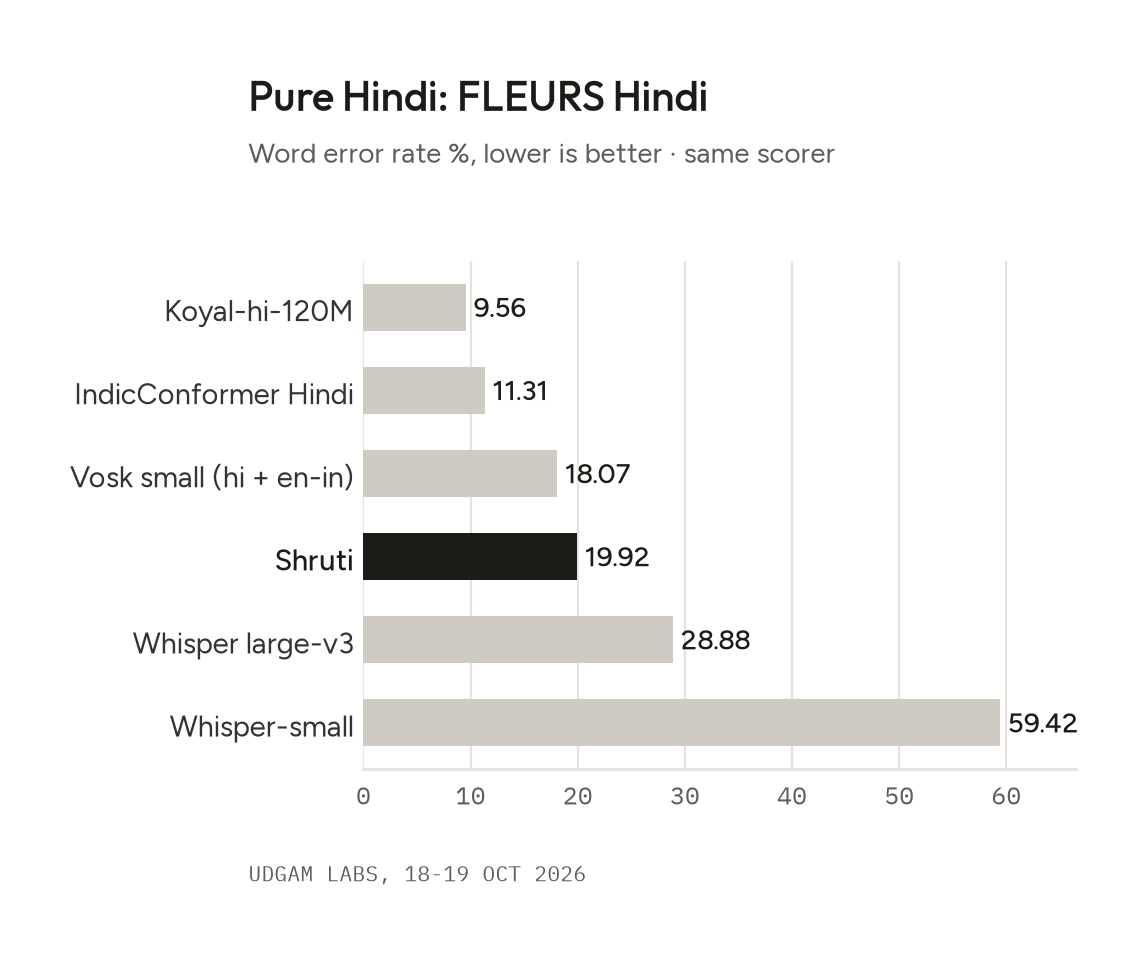
At 29.5 MB, Shruti is about 16× smaller than the Hindi-only models we measured it against, and it writes English words in English inside Hindi, the way people type Hinglish. It runs offline on a budget phone: about 1 second per sentence and 80 MB of memory on a Samsung Galaxy F62 with the native engine. In that phone’s browser, the final pass takes about a third as long as the speech. On pure Hindi, the larger Hindi-only models are clearly more accurate.
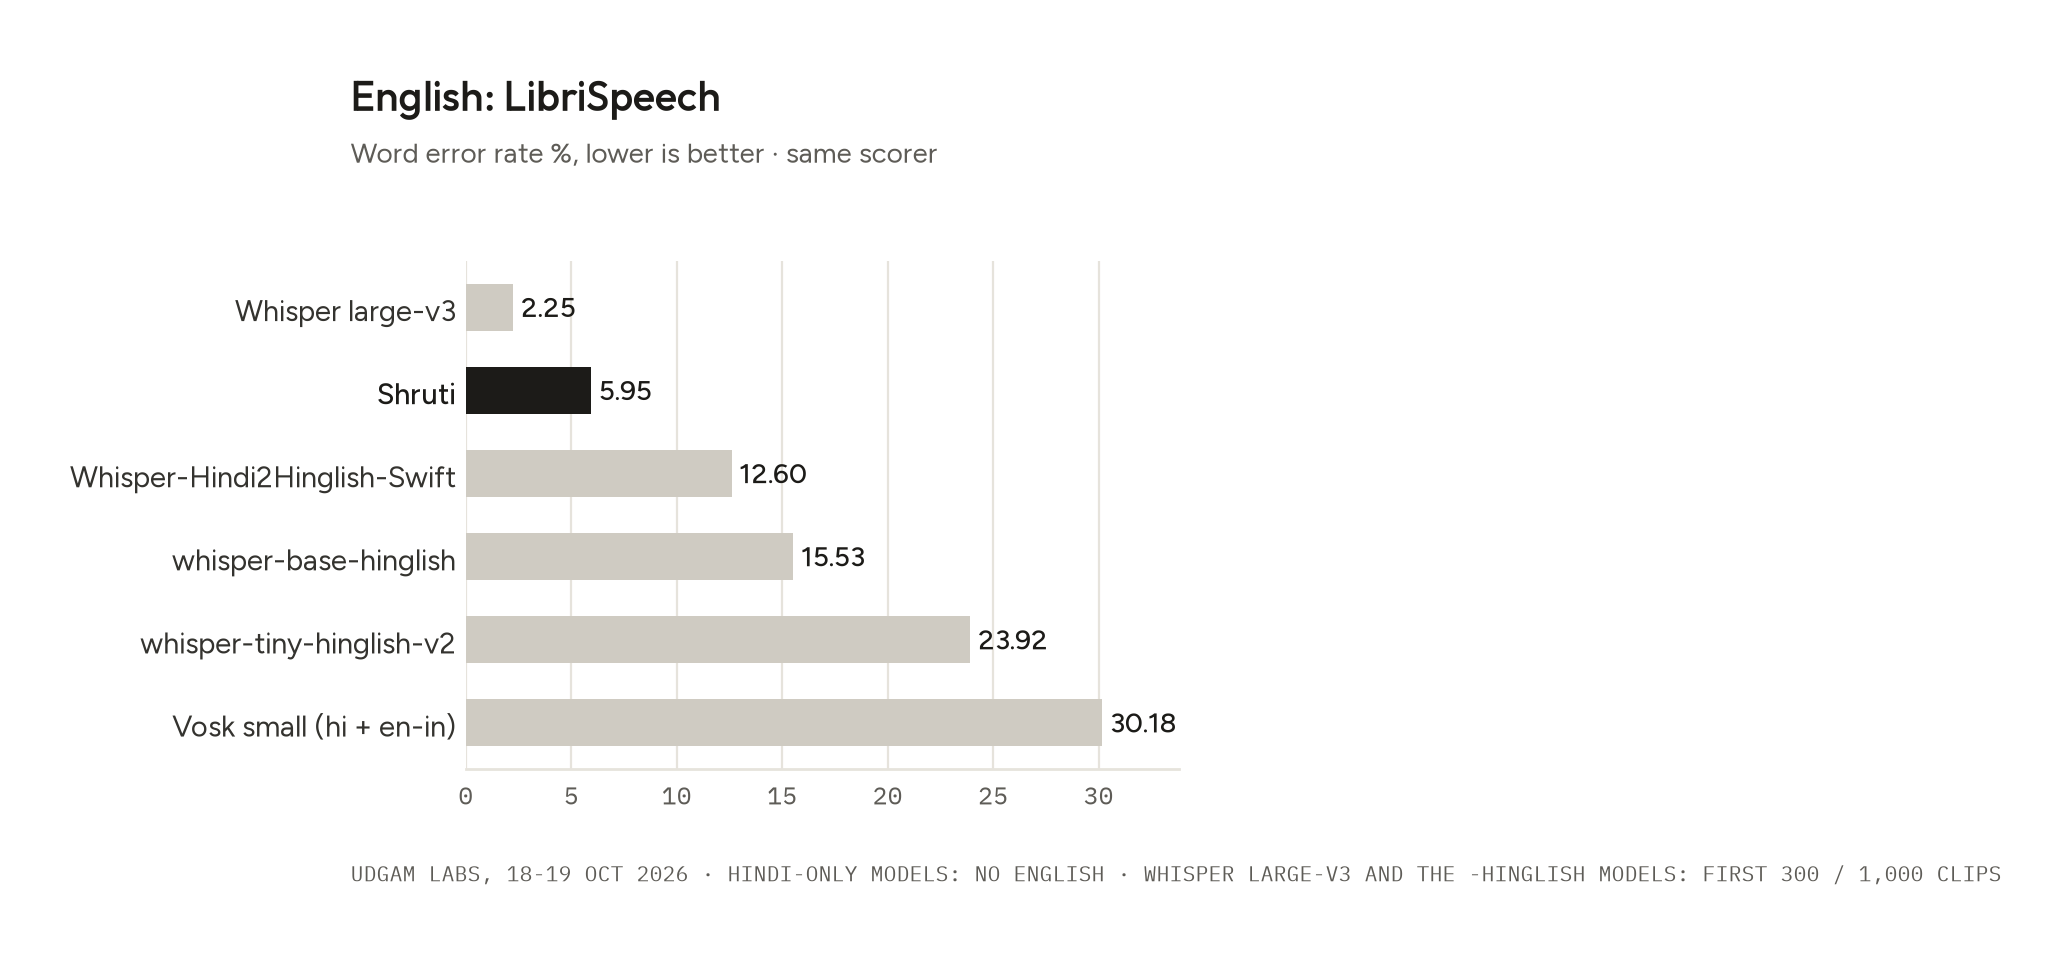
Of the open models we measured, it makes the fewest errors on Hinglish (MUCS 2021, 3,136 clips), including two Whisper models fine-tuned for Hinglish, and it stays ahead when both sides are written in Roman script.
One small file
Shruti is a single 29.5 MB file: the whole model, 55M parameters, for three ways of speaking. The Hindi-only models in our comparison are 481 and 482 MB, and Whisper-small is 971 MB. A file this size can ship inside an app or download over a phone connection, and it runs with no server at all.
It is built on Cactus Whistle, an open speech model from Cactus Compute. We fine-tuned all 55M of its weights, added 714 Devanagari vocabulary pieces, and trained it on 2,732 hours of openly licensed Indian speech.
How it compares
Word error rate, the share of words a model gets wrong, on the same test sets with the same scorer for every model. In this table Shruti is the smallest file and makes the fewest errors on Hinglish (MUCS) and on English read speech (LibriSpeech), and it invented no words on 100 silent clips. On pure Hindi, the Hindi-only models Koyal-hi-120M and IndicConformer, about 16× larger, are clearly more accurate. On Indian English (Svarah), Oriserve’s Whisper-Hindi2Hinglish-Swift is ahead.
| Model | File size | Monsoon Hindi | FLEURS Hindi | Lahaja (Hindi accents) | MUCS Hinglish | Svarah (Indian English) | LibriSpeech (English) | Words invented on 100 silent clips |
|---|---|---|---|---|---|---|---|---|
| ShrutiUdgam Labs | 29.5 MB (smallest) | 20.46 | 19.92 | 26.28 | 35.21 (best) | 22.47 | 5.95 (best) | 0 (best) |
| Koyal-hi-120MAdalat AI | 481 MB | 11.64 (best) | 9.56 (best) | 18.70 | 57.51 | Hindi only | Hindi only | 0 (best) |
| IndicConformer HindiAI4Bharat | 482 MB | 15.31 | 11.31 | 13.18 (best) | 64.48 | Hindi only | Hindi only | 88 |
| Vosk small (hi + en-in)Alpha Cephei | 139 MB | 35.75 | 18.07 | 26.60 | 61.14 | 38.51 | 30.18 | 1 |
| Whisper-Hindi2Hinglish-SwiftOriserve | 296 MB | 57.16* | n/c | n/c | n/c | 20.16 (best) | 12.60 | 1,676 |
| Whisper-smallOpenAI | 971 MB | 128.25 | 59.42 | 117.5 | – | – | – | – |
| whisper-base-hinglishabhishekgautamm | 290 MB | 65.66* | – | – | 87.05* | 27.11† | 15.53† | 500 |
| whisper-tiny-hinglish-v2abhishekgautamm | 151 MB | 70.60* | – | – | 87.73* | 34.50† | 23.92† | 500 |
Word error rate %, lower is better. Same test sets and the same scorer for every model; Monsoon Hindi with the Hugging Face Hindi leaderboard’s scorer, on the public split. Shruti was run in its on-device engine on a Mac, the other models in the same harness on a GPU pod. Measured 18–19 October 2026.
The best number in each column is in bold. Hindi only: the model does not transcribe English. n/c: not comparable, because the model writes Hindi in Roman letters only. *The model writes Roman script only, so this column mostly measures the script, not the hearing. –: not measured. The silence test uses silent clips only, not noise or music.
†First 1,500 Svarah and first 1,000 LibriSpeech clips; Shruti on the same clips scores 21.35 and 6.36.
Scored with both sides converted to Roman script by the same function, MUCS Hinglish is: Shruti 34.32, whisper-base-hinglish 43.45, whisper-tiny-hinglish-v2 44.94. The whisper-*-hinglish model cards report 28.4 and 32.0 on a 250-clip sample with their author’s own converter, which we did not run.
For context, the Hugging Face Hindi leaderboard publishes these Monsoon word error rates: Whisper large-v3 (1.55B parameters) 28.17, Whisper large-v3-turbo 40.79, Voxtral Mini 3B 22.9, Qwen3-ASR-0.6B 18.13 and IndicConformer-600M 8.47. Shruti’s 20.46 is on the public split, and the board’s own number for it may differ by a few points. An official rank needs a submission, which we have not made.
Next to Sarvam’s speech models
Two of Sarvam’s speech-to-text models for Indian languages: Sarvam Edge, which runs on its partners’ devices, and Saaras v4, a paid cloud API. We have not measured either, so this table compares what is published, not accuracy.
| Fact | Shruti | Sarvam Edge speech-to-text | Sarvam Saaras v4 |
|---|---|---|---|
| Availability | Open weights, Apache-2.0 | Closed; commercial partners only | Paid cloud API |
| Size | 29.5 MB file, 55M parameters | About 294 MB (FP16), 74M parameters (Sarvam’s figures) | Server model |
| Internet needed | No: phone, laptop or browser | No, on partner devices | Yes |
| Shown running on | Samsung Galaxy F62 (2021, about ₹18,000) | Flagship chips (for example Snapdragon 8 Gen 3) in Sarvam’s demos | Servers |
| Languages | Hindi, English, Hinglish | 10 Indian languages | 22 Indian languages and English |
| Published accuracy on shared tests | Yes, on this page | None published | Not measured by us |
Sarvam’s 294 MB is unquantised (16-bit); at 4 bits it would be roughly 37 MB. Saaras v4 is a large cloud model and is likely more accurate than Shruti, and Sarvam Edge is not available to test, so this compares facts, not accuracy.
Sources: Sarvam Edge launch post (14 February 2026) · Sarvam Edge product page · Sarvam model docs (Saaras).
On a budget phone
Samsung Galaxy F62: Exynos 9825, 6 GB of memory, Android 13. A 2021 phone that sold for about ₹18,000. Offline, on 2 threads.
- A sentence of about 7 seconds
- ~1 s
- Including loading the model
- A 60-second recording
- 9.5 s
- 6.3× faster than real time
- Peak memory
- 80 MB
- Over the same runs
42 of 51 transcripts were identical to the Mac’s; the rest differ by a letter or two.
- Browser engine (WebAssembly, one thread, run in Node on a Mac)A 9.6 s clip in 0.45 s, with transcripts identical to the native engine
- Hugging Face Space (a shared 2-core CPU)A 2.8 s clip in 0.35 s
Good fits, and where it falls short
Good fits
- Voice input in apps where the audio should stay on the device.
- Hinglish dictation, notes and search, with English words kept in English.
- Phones with little memory, and places with a weak connection or none.
- Live text from a microphone, with the engine’s streaming calls.
Where it falls short
- Less accurate than larger Hindi-only models on pure Hindi. Koyal-hi-120M and IndicConformer, about 16× larger, make fewer errors on every Hindi test: 9.56% and 11.31% on FLEURS Hindi against Shruti’s 19.92%.
- Weaker on Hindi accents. On Lahaja, IndicConformer makes 13.18% word errors and Shruti 26.28%.
- Hindi comes out in Devanagari only. It does not write Hindi in Roman letters.
- Tested on silence, not on noise or music. It invented no words on 100 silent clips.
- Not tested on Windows by us. The engine has a Windows build; we measured on a Mac, Linux, an Android phone and WebAssembly.
- No leaderboard rank. Our Monsoon number is on the public split; we have not made an official submission.
The name
Shruti
श्रुति
Shruti (श्रुति) is Sanskrit for “that which is heard”.
A small model that listens, on your device.
The model
- Parameters
- 55M
- File
- 29.5 MB, one .cact file (W4A8: 4-bit weights, 8-bit activations)
- Built on
- Cactus Whistle by Cactus Compute (Apache-2.0). All 55M weights fine-tuned; 714 Devanagari vocabulary pieces added
- Training data
- 2,732 hours of openly licensed Indian speech (see the credits below)
- Languages
- Hindi (in Devanagari), English, and Hinglish with English words in Latin script
- Input
- 16 kHz mono audio of any length: one pass up to 30 s, longer audio in 30 s windows
- Engine
- Cactus needle (Apache-2.0) on Mac, Linux, Windows, Android, iOS and in the browser (WebAssembly). Measured by us on a Mac (Apple silicon), Linux (x86), an Android phone and WebAssembly; not tested by us on Windows
- Licence
- Apache-2.0 (weights), keeping Cactus’s notice
Use it in your app
Shruti runs in Cactus’s open-source needle engine. Download the engine for your platform and the model file, and pass it a WAV file or 16 kHz audio.
# Command line (Mac, Linux, Windows)
# Engine: huggingface.co/Cactus-Compute/needle3, your platform
# Model:  huggingface.co/udgamlabs/Shruti, shruti.cact
./needle --model shruti.cact --audio clip.wav
# for speech that is only English: --audio-language en

# Python
pip install cactus-needle

import needle
shruti = needle.Whistle(weights="shruti.cact")
print(shruti.transcribe("clip.wav")["text"])- Android, iOS and the web: call the engine’s C API.
needle_loadtakes the model file,needle_transcribea clip, andneedle_stream_transcribe_processabout a second of live audio at a time. The demo on this page makes the same calls, from WebAssembly in a Web Worker. - Leave the language unset for Hindi and Hinglish: detection does as well as setting it on Hindi, Hinglish, accented Hindi and US English. Set English when the speech is only English with an Indian accent, which detection often takes for Hindi. On a subset of Svarah: 21.13% word errors with English set, 25.75% detected.
- Keywords, one per line, favour the names, places and product words your users say.
- Cactus’s prebuilt engines and Python package send usage telemetry by default; set
NEEDLE_TELEMETRY=0andDO_NOT_TRACK=1to turn it off. The WebAssembly engine on this page makes no network requests of its own.
Credits
Shruti is built on Cactus Whistle and runs in the needle engine, both by Cactus Compute under Apache-2.0. The engine files on this page are Cactus’s WebAssembly build, unmodified, served with its licence and notice. Shruti learned from these openly licensed speech datasets, all of which allow commercial use:
- AI4Bharat IndicVoicesCC-BY-4.0
- ARTPARK-IISc VaaniCC-BY-4.0
- AI4Bharat ShrutilipiCC-BY-4.0
- AI4Bharat NPTELCC-BY-4.0
- AI4Bharat KathbathCC-BY-4.0
- Mozilla Common Voice 17: English, India and South Asia accentsCC0
- LibriSpeechCC-BY-4.0
- MUCS 2021 Hinglish, via dianavdavidson/MUCS-HinglishCC-BY-4.0 on the dataset card; the original is CC-BY-SA-4.0
- AI4Bharat Rural_Women_ASR_v2CC-BY-4.0
- Google FLEURS, Hindi train splitCC-BY-4.0
Weights and links
- Shruti on Hugging Face
The model file (shruti.cact) and model card
- Hugging Face Space
The demo on a server CPU
- Shruti on GitHub
Runnable examples (Python, command line, a web page you can host), checksums and the full comparison
- Cactus needle engines
Prebuilt engines for each platform, and the WebAssembly build
- Cactus Whistle
The speech model Shruti is built on
- needle on GitHub
The engine’s source and documentation
Shruti’s weights are released under Apache-2.0, built on Cactus Whistle (Apache-2.0, Cactus Compute). The model card lists every training dataset and its licence.