A frontier technology lab turning research into useful tools.

We develop AI models, test emerging technologies, and build practical software for people around the world. Our work brings together open model releases and independent products, with Udgam Labs as their home.

ideas cycle ≈ 12s

Models · Open releases

Small models. Measured progress.

Focused AI models, shared with open weights, documentation and measured results. Explore what each model does, where it does well and where it still makes mistakes.

New · Public release · From scratch · Maths word problems

Lilavati

Pocket Mathematician

A 95M-parameter model, trained from scratch, that solves maths word problems by writing a short Python program and running it. Every answer comes with the program behind it, so you can check the working.

Parameters
95M
Licence
Apache-2.0
Runs on
PyTorch and transformers, on a laptop CPU
A saved output · Real Lilavati answer
“A chai stall sells 45 cups of tea in the morning and twice as many in the evening. Each cup costs 12 rupees. How many rupees does the stall earn in a day?”

The program it wrote

morning_sales = 45
evening_sales = morning_sales * 2
cup_price = 12
total_sales = (morning_sales + evening_sales) * cup_price
result = total_sales
return result

Running it gives

1,620

GSM8K, first try
54.7%
With the checker
72.3%

On GSM8K, the standard test of grade-school maths word problems, it solves 54.7% on its first try with its program executed, and 72.3% when Lilavati-Checker, a second 95M model, weighs 48 tries. Good at shopping, discounts and tax, speeds, averages, interest and areas; weak at numbers that should be ignored, working backwards and unit conversions.

A small research model: answers can be wrong, so check the program. See the results and limitations
Public release · From scratch · Text to image

Chitra Tiny

A 212M-parameter English text-to-image model that makes 256×256 pictures from a sentence. Trained from scratch on about 4.7 million public-domain and CC0 images, it runs on a laptop in about three seconds per image.

Weights
0.85 GB
Output
256×256
Runs on
PyTorch on NVIDIA GPUs, Apple silicon or CPU
A saved output · Seed 0, first try
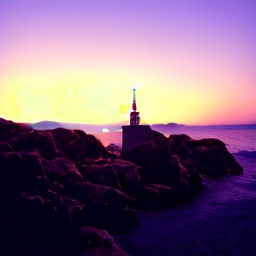
“a lighthouse on a rocky coast at sunset”

The picture it made

Chitra Tiny output: a lighthouse on dark rocks against a purple and yellow sunset sky

256×256, shown at its real resolution. seed 0 · guidance 7 · 50 steps.

CLIP score
26.2
GenEval
0.219

Its pictures match their captions nearly as well as real photos do (CLIP 26.2 against 27.5). It is good at photos, paintings, landscapes, buildings and vehicles, and weak at composing specific objects: on GenEval it reaches about half of Stable Diffusion 1.5 (0.426), a model four times larger.

A small research model with no safety filter of its own. See the results and limitations

Public release · From scratch

Udgam-384M

A 384M-parameter English model for tool calling inside apps, on the device itself. Trained from scratch, it turns requests into function calls, documents into JSON and tasks into shell commands for review, and recognises when to ask or decline.

Smallest file
238 MB (4-bit GGUF)
Context
4,096 tokens
Runs in
Ollama, LM Studio, llama.cpp, MLX, transformers
A recorded example · App action
“Wake me up at 6:45 tomorrow, label it gym.”

The tool call it returned

Tool
set_alarm
time
06:45
label
Gym

Your app checks the call, sets the alarm and sends the result back. The model takes no action by itself. Recorded with Ollama · Q8_0 · thinking off.

Relevance · held-out
75%
BFCL v3 simple
60%

Among the tiny open models we compared, it is strongest at deciding whether to act: declining when no tool fits, asking for missing details, schema-valid JSON and shell behaviour. It is behind Granite 4.0 350M (88–91%) and Qwen3-0.6B (80%) on exact calls in BFCL v3, and on IFEval.

Not safety-hardened: use it where your app decides which tools exist and confirms risky actions. See the comparison and limitations

Experimental v0.1.0 · From scratch

Udgam English 125M v0.1.0

A small English language model trained from random weights, with a vocabulary fitted on its training text. We share the base and conversation variants, the recipe, and the results — including the missed performance target.

Variants
Base + conversation
Context
2,048 tokens
Fixed suite · 2,500 questions
ModelAccuracy
Udgam English 125M · base45.72%
Udgam English 125M · conversation46.40%
Sarvam-168.08%
SmolLM2-135M51.76%
SmolLM2-360M57.40%

Macro accuracy on a fixed 2,500-question suite: 500 items each from ARC-Challenge, HellaSwag, PIQA, BoolQ and WinoGrande. These scores describe this protocol and these checkpoints, not general assistant quality.

Performance target missed. This is a research release for studying and adapting a small model. The results do not support use as a reliable general assistant.

Experimental release · 0.6B

Udgam Hinglish Commands

Turns short English and Romanized Hinglish requests — Hindi and English mixed in Latin letters — into a structured intent and labelled details that an app can use.

Fine-tuned Qwen3-0.6B · LoRA adapter

Eight evaluated command domains

  • Alarms
  • Events
  • Messaging
  • Music
  • Navigation
  • Reminders
  • Timers
  • Weather
A recorded example · Hinglish
“bed time ka alarm kab hai?”

The model's interpretation

Intent
Look up an alarm
Alarm name
bed time

This saved result matches the benchmark reference. Your app would look up the alarm and decide how to respond. No action is taken by this model.

View saved model output
[IN:GET_ALARM [SL:ALARM_NAME bed time ] ka alarm kab hai? ]

htop-test-004074-hinglish

Original Qwen
9.90%
Udgam adapter
54.88%

Complete interpretations matching the human reference on 13,026 held-out commands, paired in English and Romanized Hinglish. Both used the same prompting setup. This measures one parsing task, not general language ability.

Experimental: it still makes mistakes and is not a general chatbot. Read the benchmark and limitations

How the lab works

From a question to something useful.

01 · Source

A question worth testing

Each experiment begins with a focused question about what emerging technology can make possible for people around the world.

02 · Stream

Build, test, measure

We build a working version and evaluate it against a clear starting point. Results and failure cases guide what we develop next.

03 · Delta

Share the work

Model releases include open weights, documentation and evaluation details. Products get their own identity and roadmap, with Udgam Labs as their origin.

About

A small lab that runs on experiments.

Udgam Labs is a frontier technology lab building AI models and software for people everywhere. We investigate emerging models, tools and hardware, build focused experiments, and measure what they can do. We share model releases with open weights, benchmarks and limitations. Products that grow out of the lab develop their own names and roadmaps.

Udgam Labs was founded in 2024 by Jitesh Kumar Prasad (LinkedIn, X), who leads its research and products. The lab operates through two companies: Udgam Labs LLP in New Delhi, India, where the work began, and Udgam Labs, Inc., its US subsidiary, incorporated in Delaware.

The name is Sanskrit for origin — the source of a river. The mark is that source: one point, then many streams.

20+
Experiments run
10+
Built, not launched
3
Products featured
2024
Founded
Contact

Have a question or a partnership in mind?

We work with teams anywhere on using our models and on small custom models, fine-tuned or trained from scratch for a specific task. Email is best for anything detailed. Replies usually within 24–48 hours.